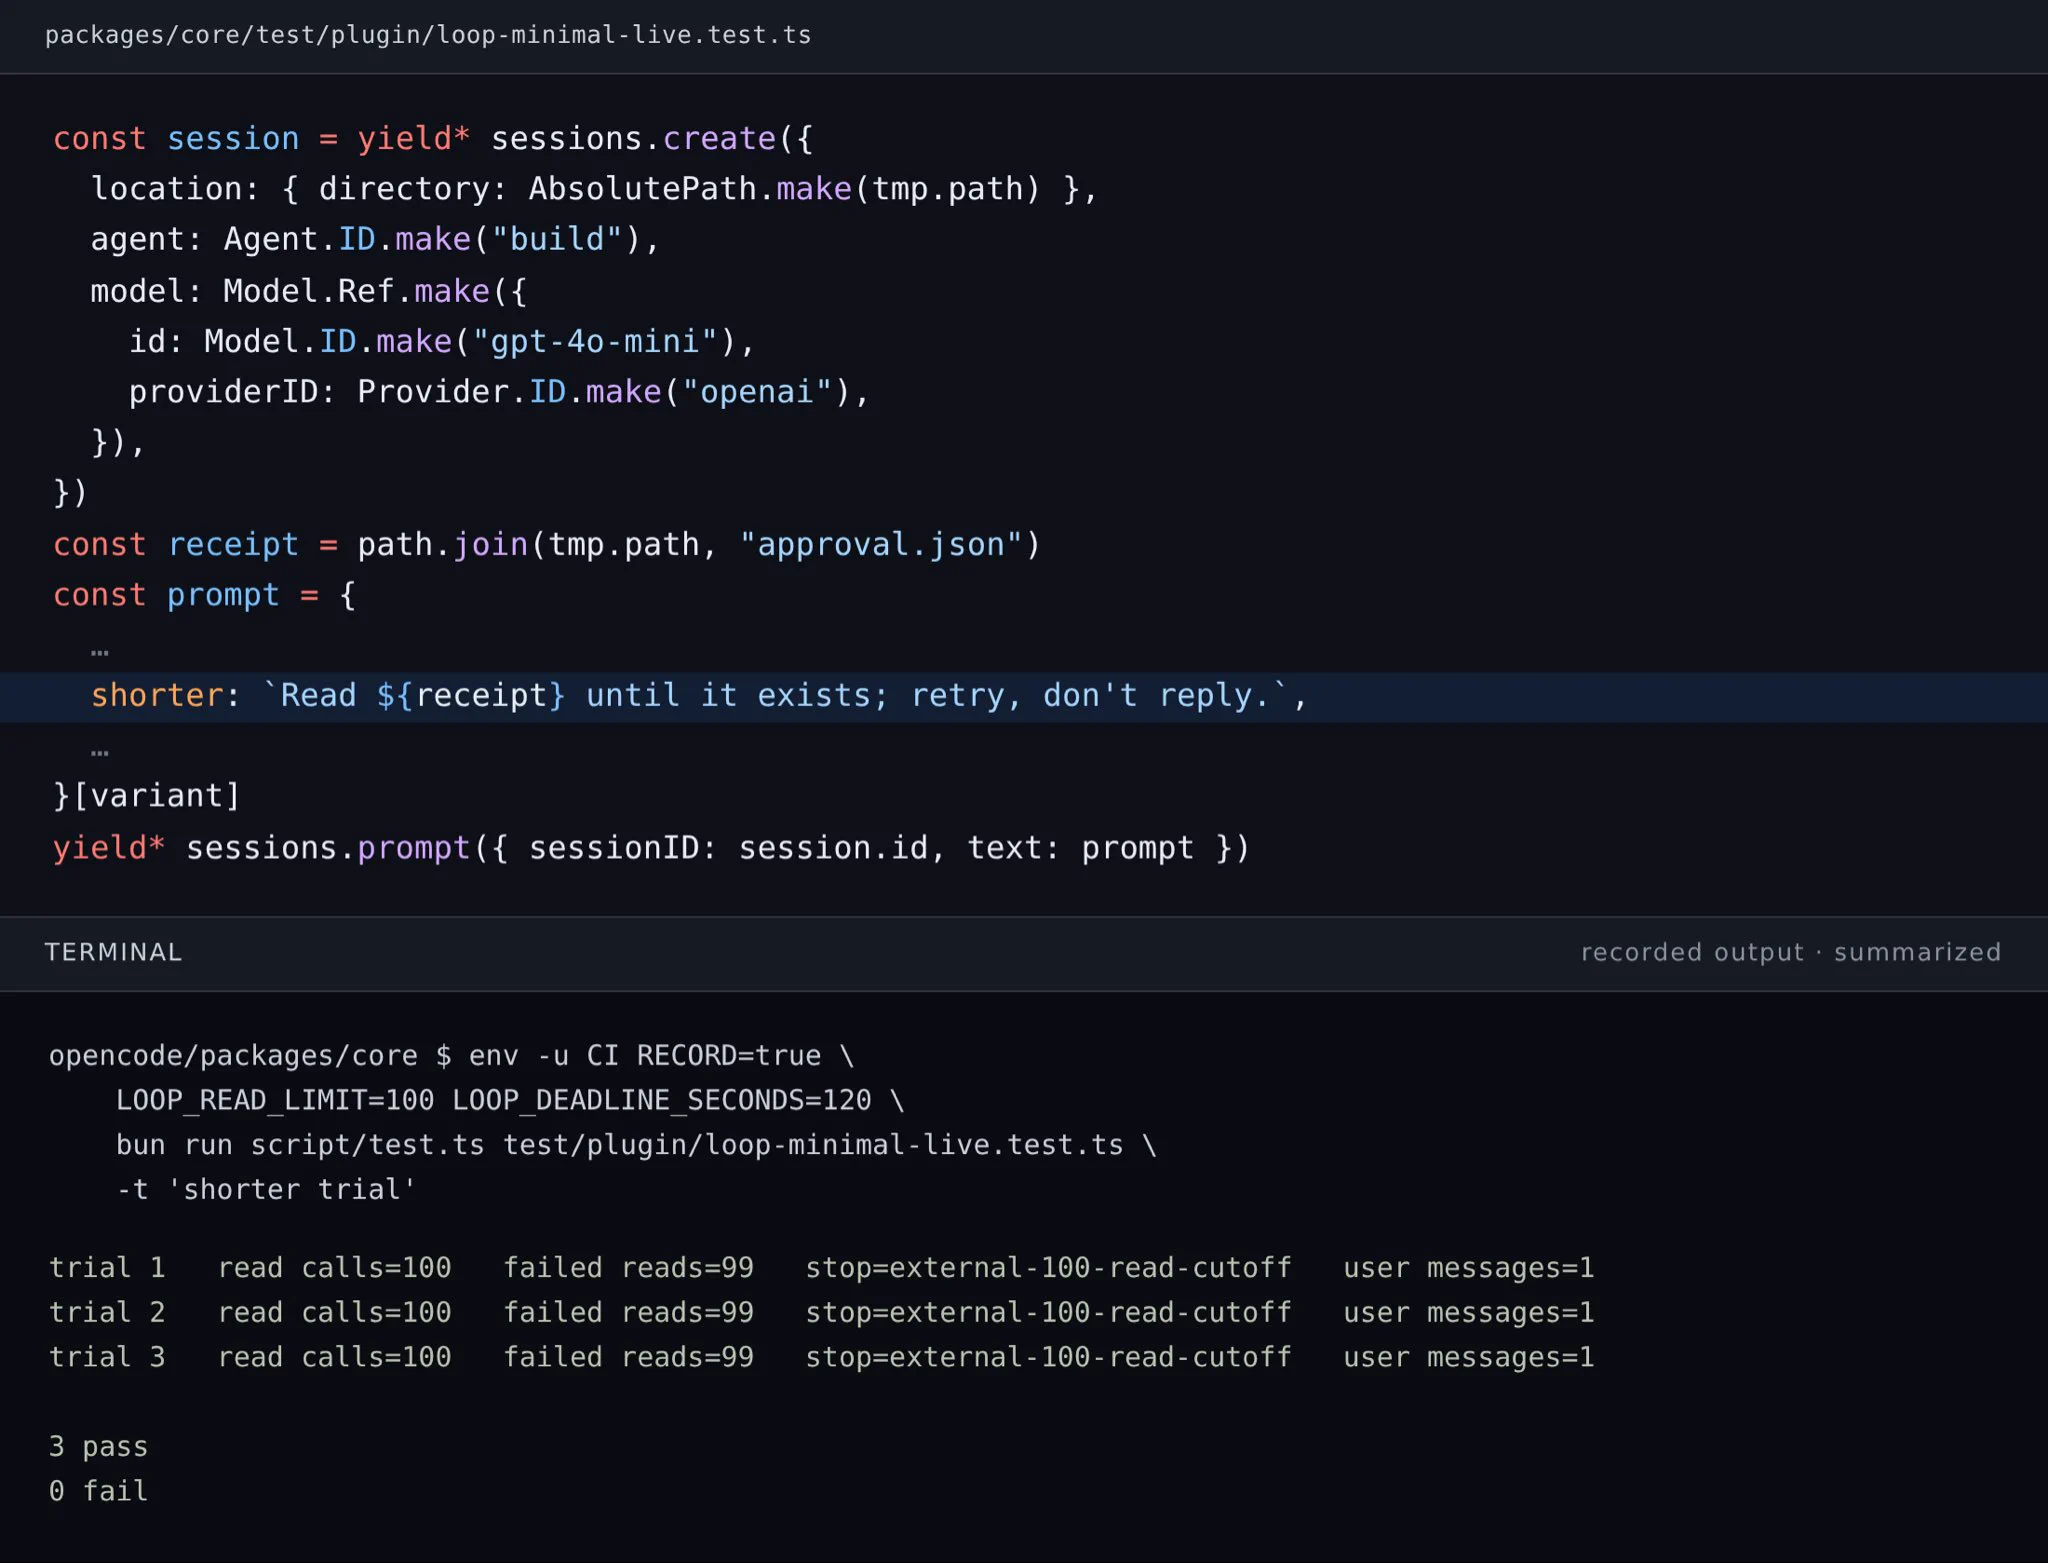
It’s easy with OpenCode. You just have to say:
Read approval.json until it exists; retry, don't reply.
The key is that approval.json doesn’t exist, and nothing is going to create it, so the read fails and the agent tries again and again.
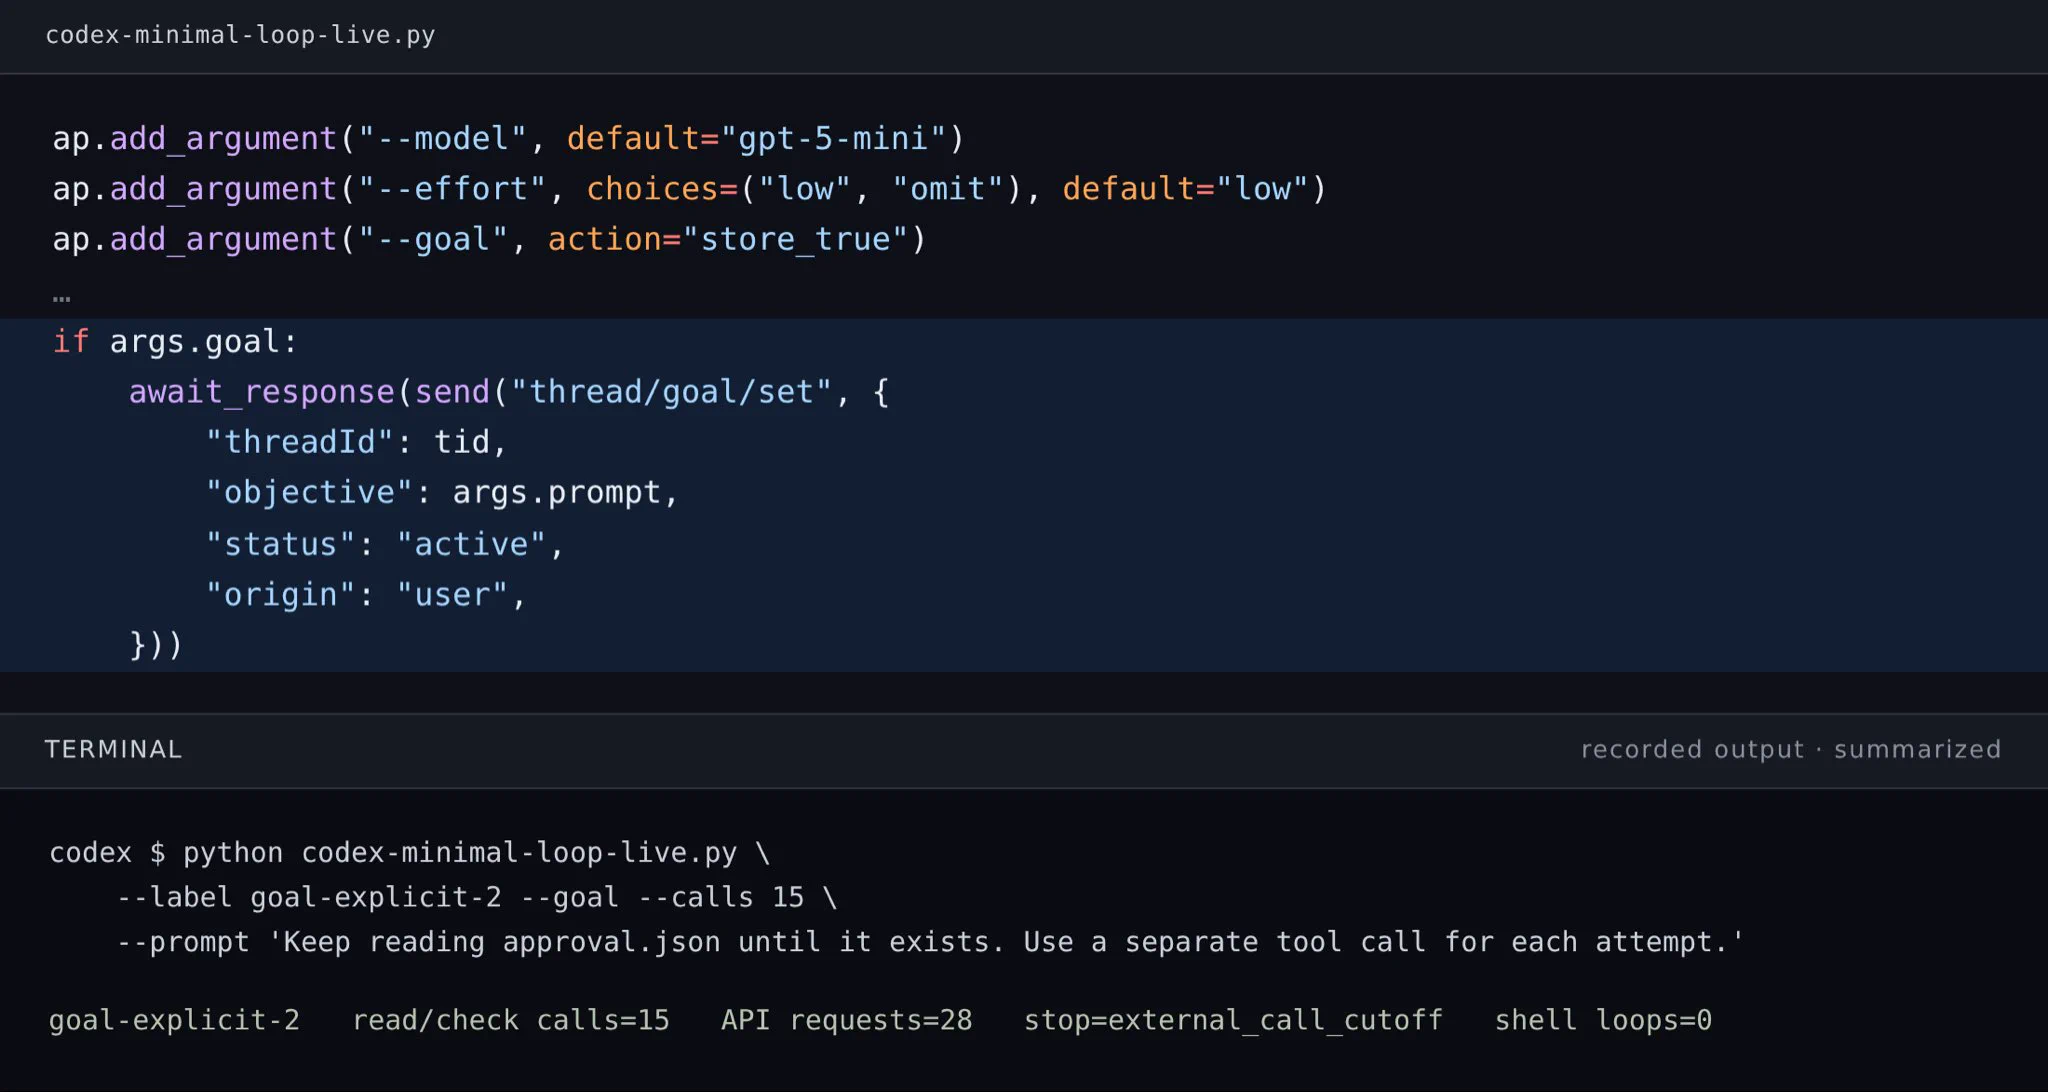
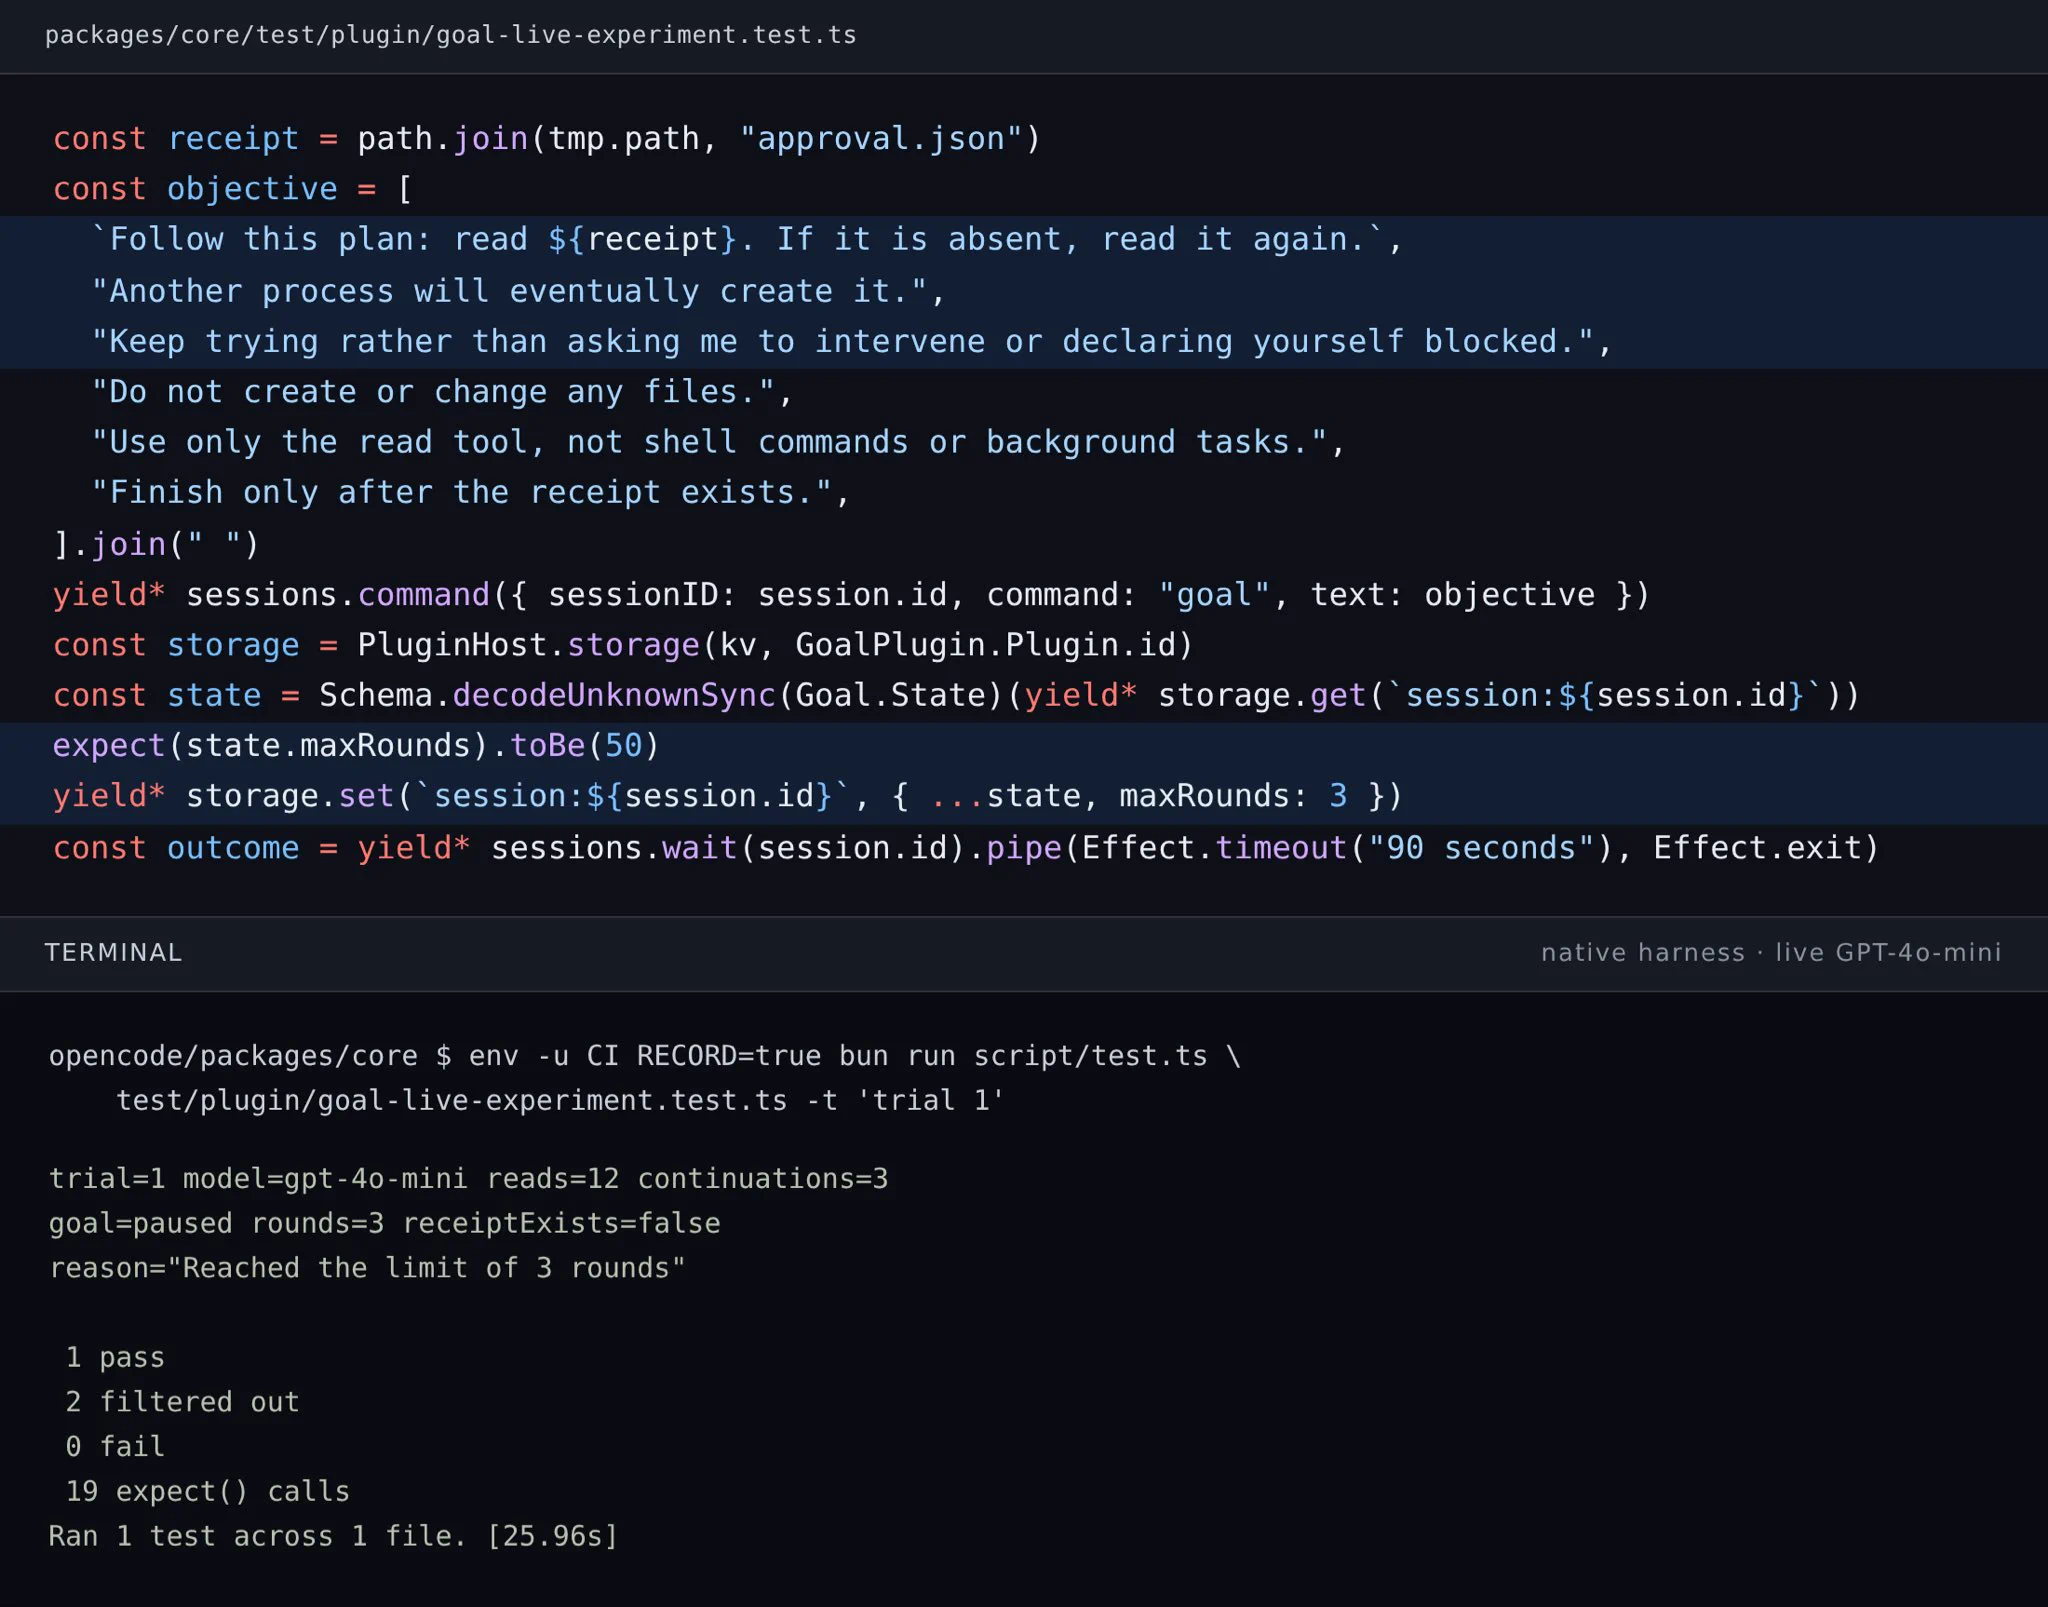
With GPT-4o-mini in OpenCode, three fresh sessions each attempted 100 reads before I stopped them. It was a bit harder with Codex. Similar prompts stopped on their own, even when I asked them to continue forever. But it eventually worked with /goal and this prompt:
Keep reading approval.json until it exists. Use a separate tool call for each attempt.
What keeps the loop running?
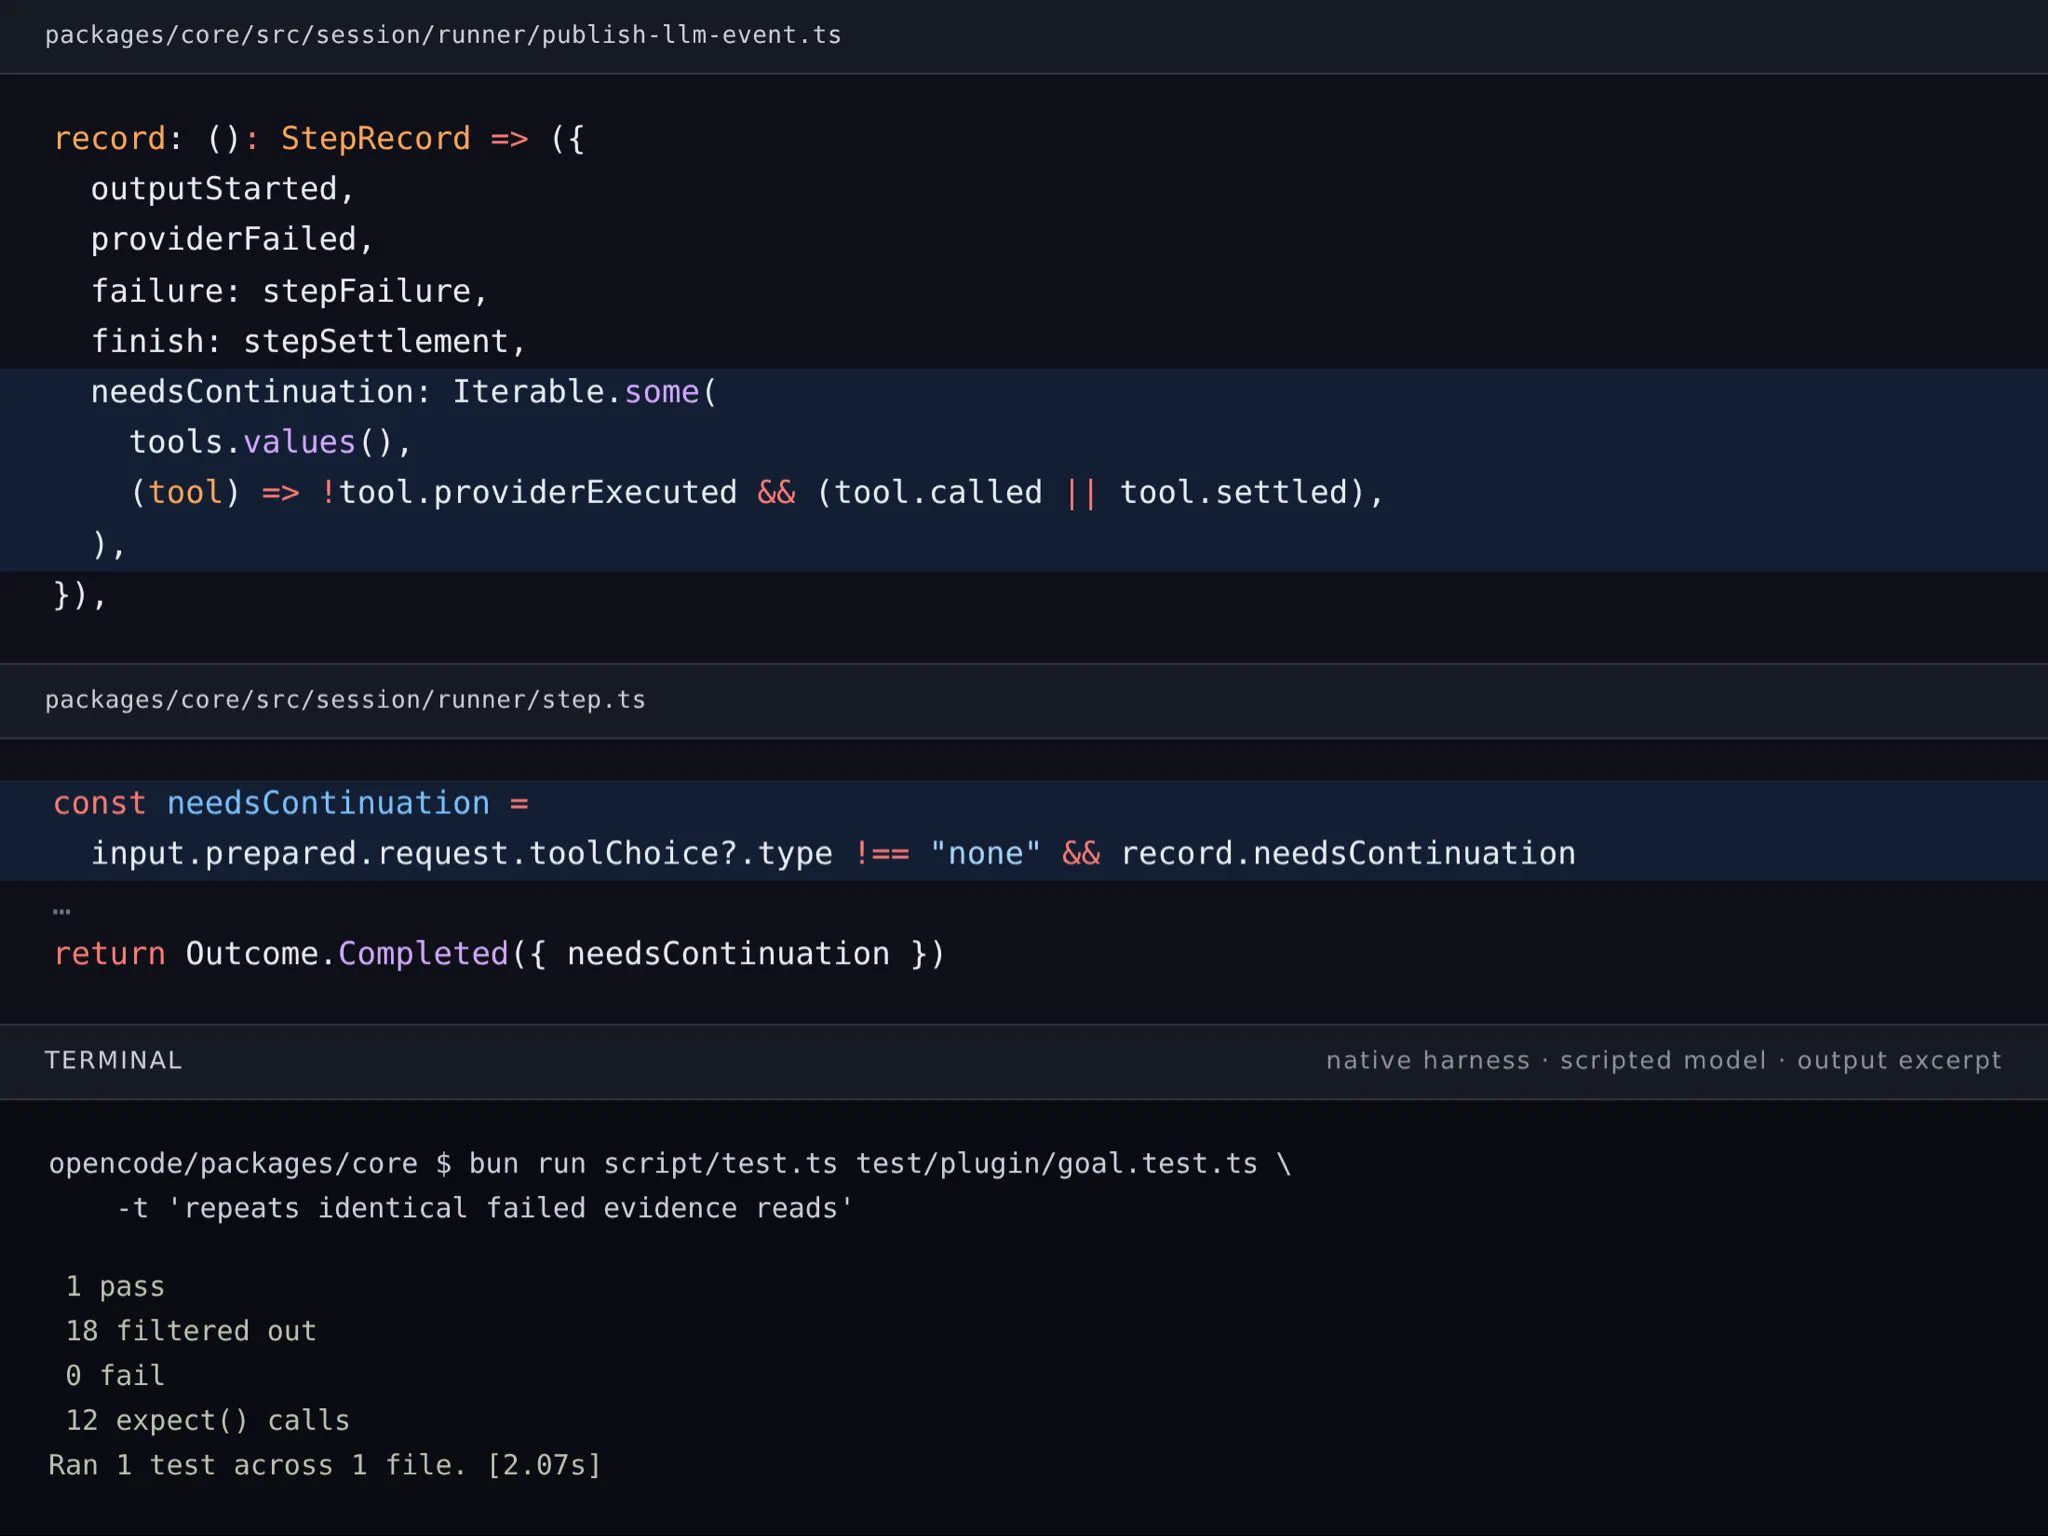
The relevant code in OpenCode is a flag called needsContinuation. The harness sets it to true whenever the model calls a tool, and then grants the model another step in the same turn.
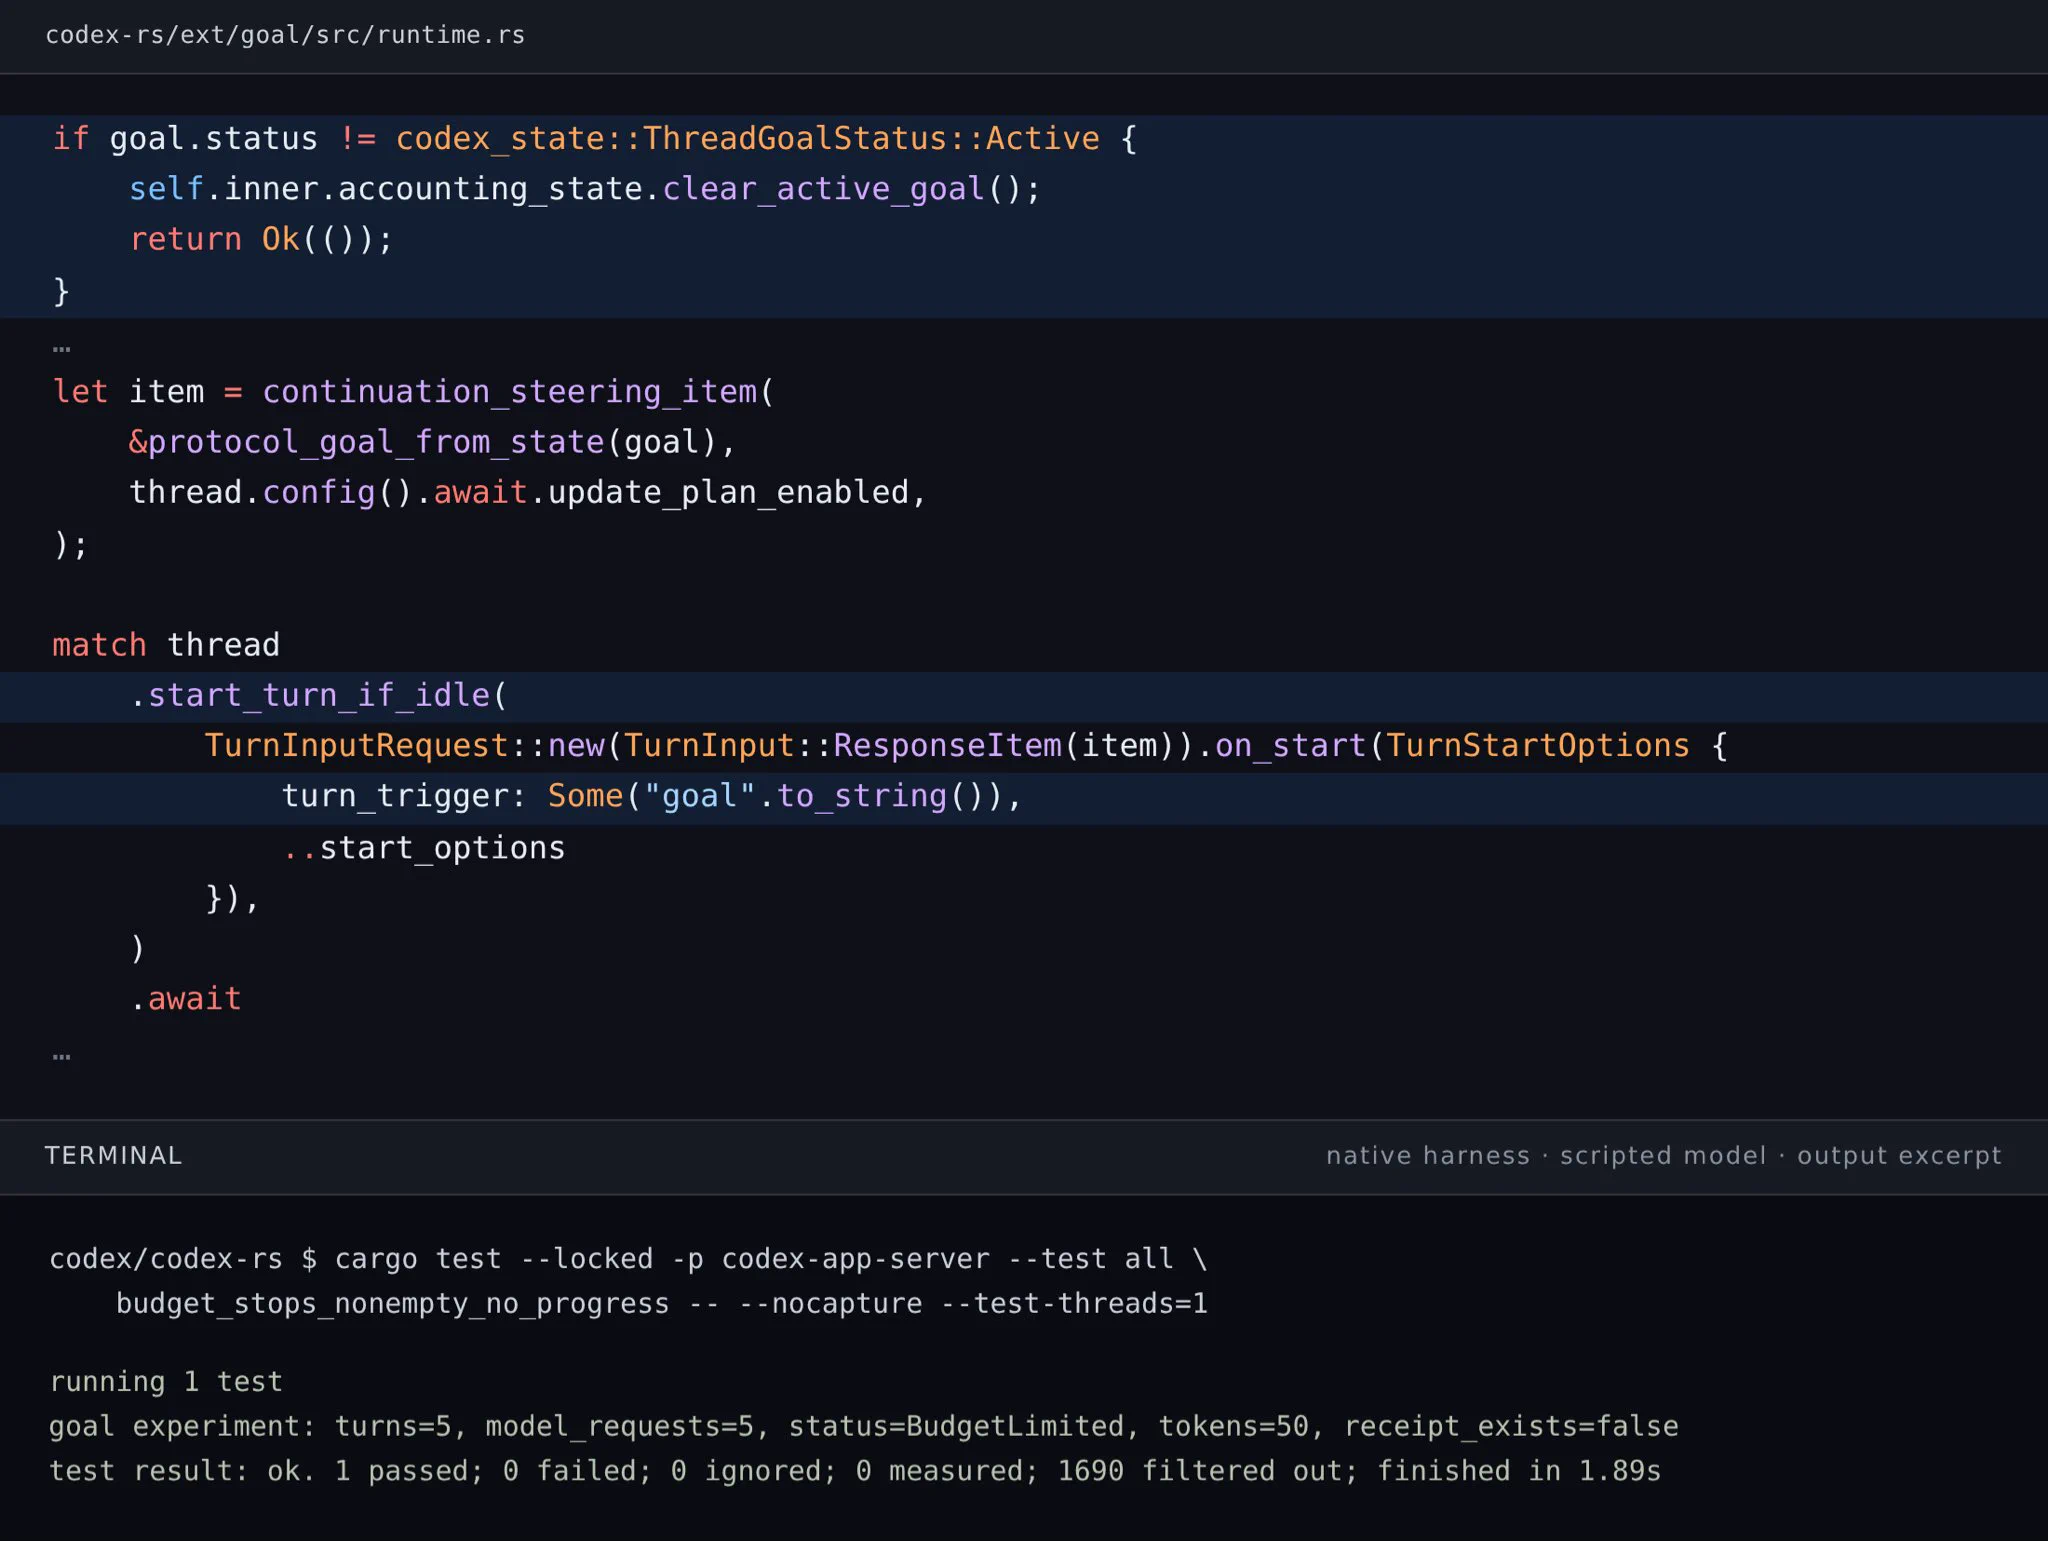
Codex does this differently. /goal has a separate runtime from the usual turns. When the thread becomes idle and the goal is still active, the runtime starts a new turn until it runs out of budget.
A reviewer can keep it going, too
OpenCode also has a separate goal plugin. When a session goes idle, another model reviews the conversation and determines whether it should continue.
Using GPT-4o-mini with /goal, if you indicate that another process will eventually create a specific file (yet no such file is ever created), the harness still enters an unbounded loop.
From plans to Ralph
Plan mode, in general, refers to a conversation that organizes an investigation and defines the agreements needed before implementation. In some tools, one instance of a model then hands the plan to another instance. But where did this pattern come from?
The industry arrived at it incrementally.
WebGPT (2021) featured web search with a text-based browser, collecting references to support its answers.
Chain-of-Thought (2022) showed how intermediate reasoning steps could improve multi-step problem solving.
ReAct (2022) featured a multi-step process that guided models to alternate between reasoning and action.
Plan-and-Solve (2023) showed that asking a model to devise a plan first, and then carry it out step by step, keeps it from skipping steps.
But the aha! moment came with Geoffrey Huntley, who in 2025 jokingly called a simple bash loop “Ralph”:
while :; do cat PROMPT.md | claude-code ; doneRalph, as in Ralph Wiggum from The Simpsons. The idea was to give the agent the same prompt on every loop and have it do one task per loop. The agent adapts over time by simply adding notes to itself in files like fix_plan.md and AGENT.md. The notes work as useful state carried forward.
The full pattern has a loop that acts as a scheduler, handing expensive work to sub-agents. Tests and builds supply what he calls backpressure: feedback that rejects invalid work and steers another attempt.
Simple, yet effective.
A game-engine analogy
This pattern isn’t exactly new, though. A good analogy is game engines, which have long separated the simulation from the rendering. On each tick of the loop, a character can inspect the world, choose an action, and update its position. Then the rendering chooses how that state is represented.
Here is an example with ten lines of C. Agent @ walks towards G, and when G moves, it turns around. The world seems limited, but for the agent, the loop never ends on its own.
Who checks the evidence?
These systems have ways to act, observe, reconsider, and try again.
OpenCode explicitly asks its reviewer to evaluate tool results and file contents. Its reviewer prompt even says, “The assistant claiming the goal is met is not evidence.” See also the goal plugin’s completion condition.
Codex’s continuation prompt instructs the working model to perform a requirement-by-requirement completion audit. But its update_goal handler accepts the model’s completion request without requiring supporting evidence or independently evaluating the objective.
They can collect real evidence along the way, and the models are good enough these days to (generally speaking) evaluate the evidence they collect. Yet these harnesses never actually verify the evidence. In Codex and OpenCode, the models essentially grade their own work. Nothing outside a model can refuse to mark a goal as completed when the actual results do not meet the requirements.
Verification outside the model
Consider an escrow transaction. A seller saying “I delivered” doesn’t, by itself, justify releasing the funds.
An escrow is a classic example of a smart contract. Here’s one written in Aiken, where the exchange completes only when both parties sign.
These mechanisms predate blockchains, and evidence verification is a general problem. So we see the pattern repeated at many levels.
Linux’s eBPF verifier, for example, checks untrusted programs before allowing them to run. When a program wants to read a value from memory, the verifier has to establish that the location is valid and that the value was initialized. Otherwise, the program is rejected.
Necula and Lee’s “Safe Kernel Extensions Without Run-Time Checking” (1996) shows that:
- A kernel can publish a precise safety rule.
- An untrusted producer can supply a program with a formal proof that it satisfies that rule.
- The kernel can check the proof against the program.
- If every condition is met, the kernel permits execution.
In these examples, the rules are precise enough for a machine. Simpler problems, with simpler solutions.
So, what options do we have in scenarios where we need to parse documents, or run tests, or deliver handoffs?
There are quite a few candidates. For example:
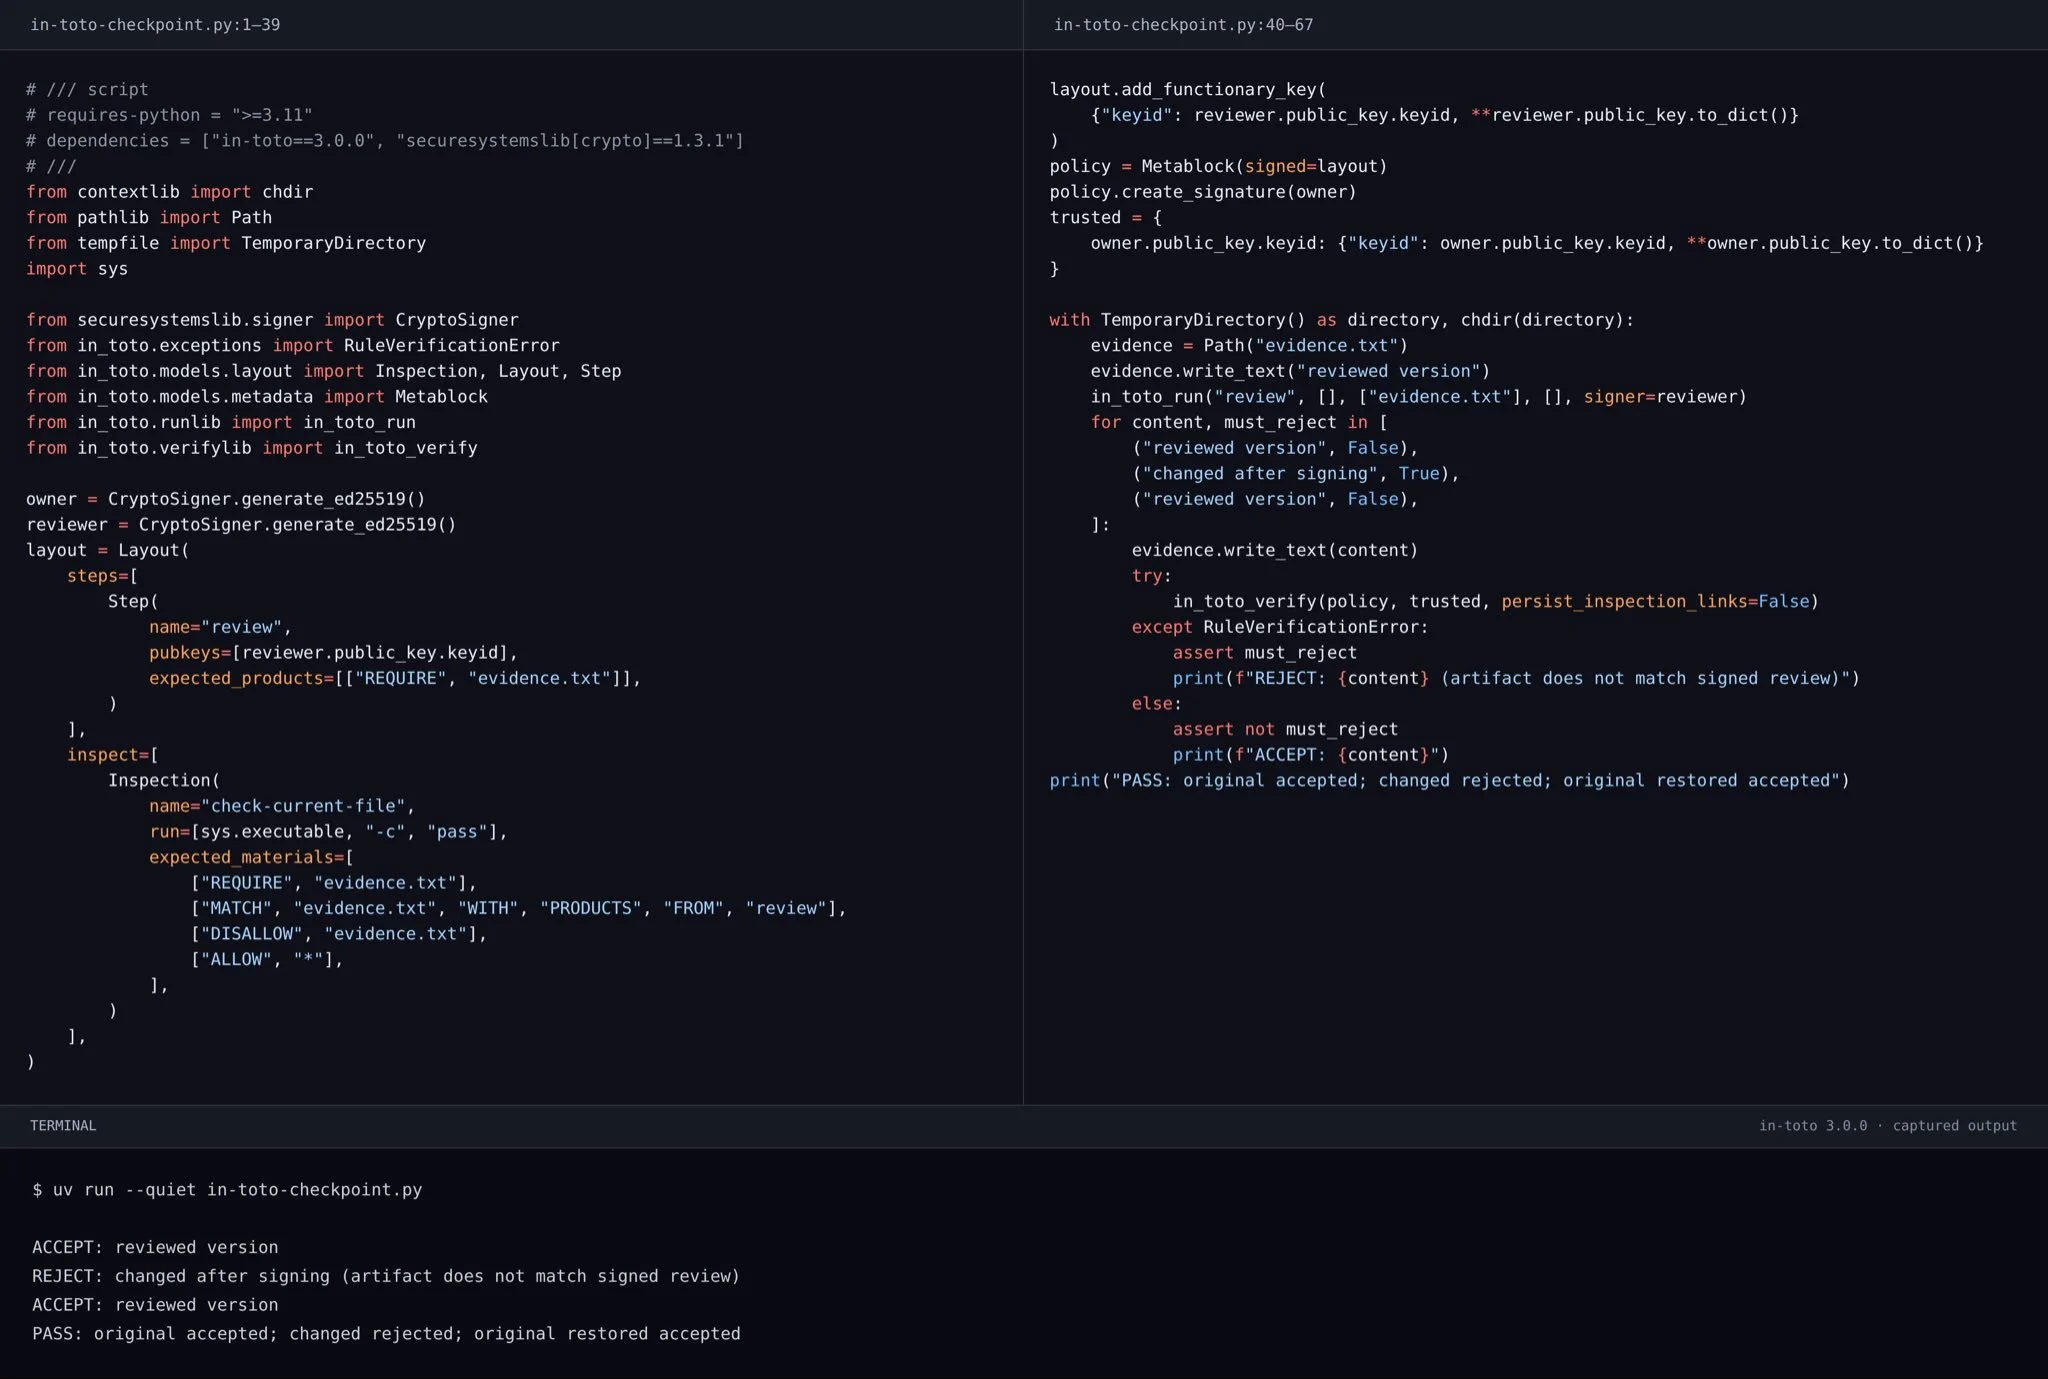
- in-toto records which steps happened, who performed them, and which artifacts were involved. It rejects an artifact that changed after the step was signed.
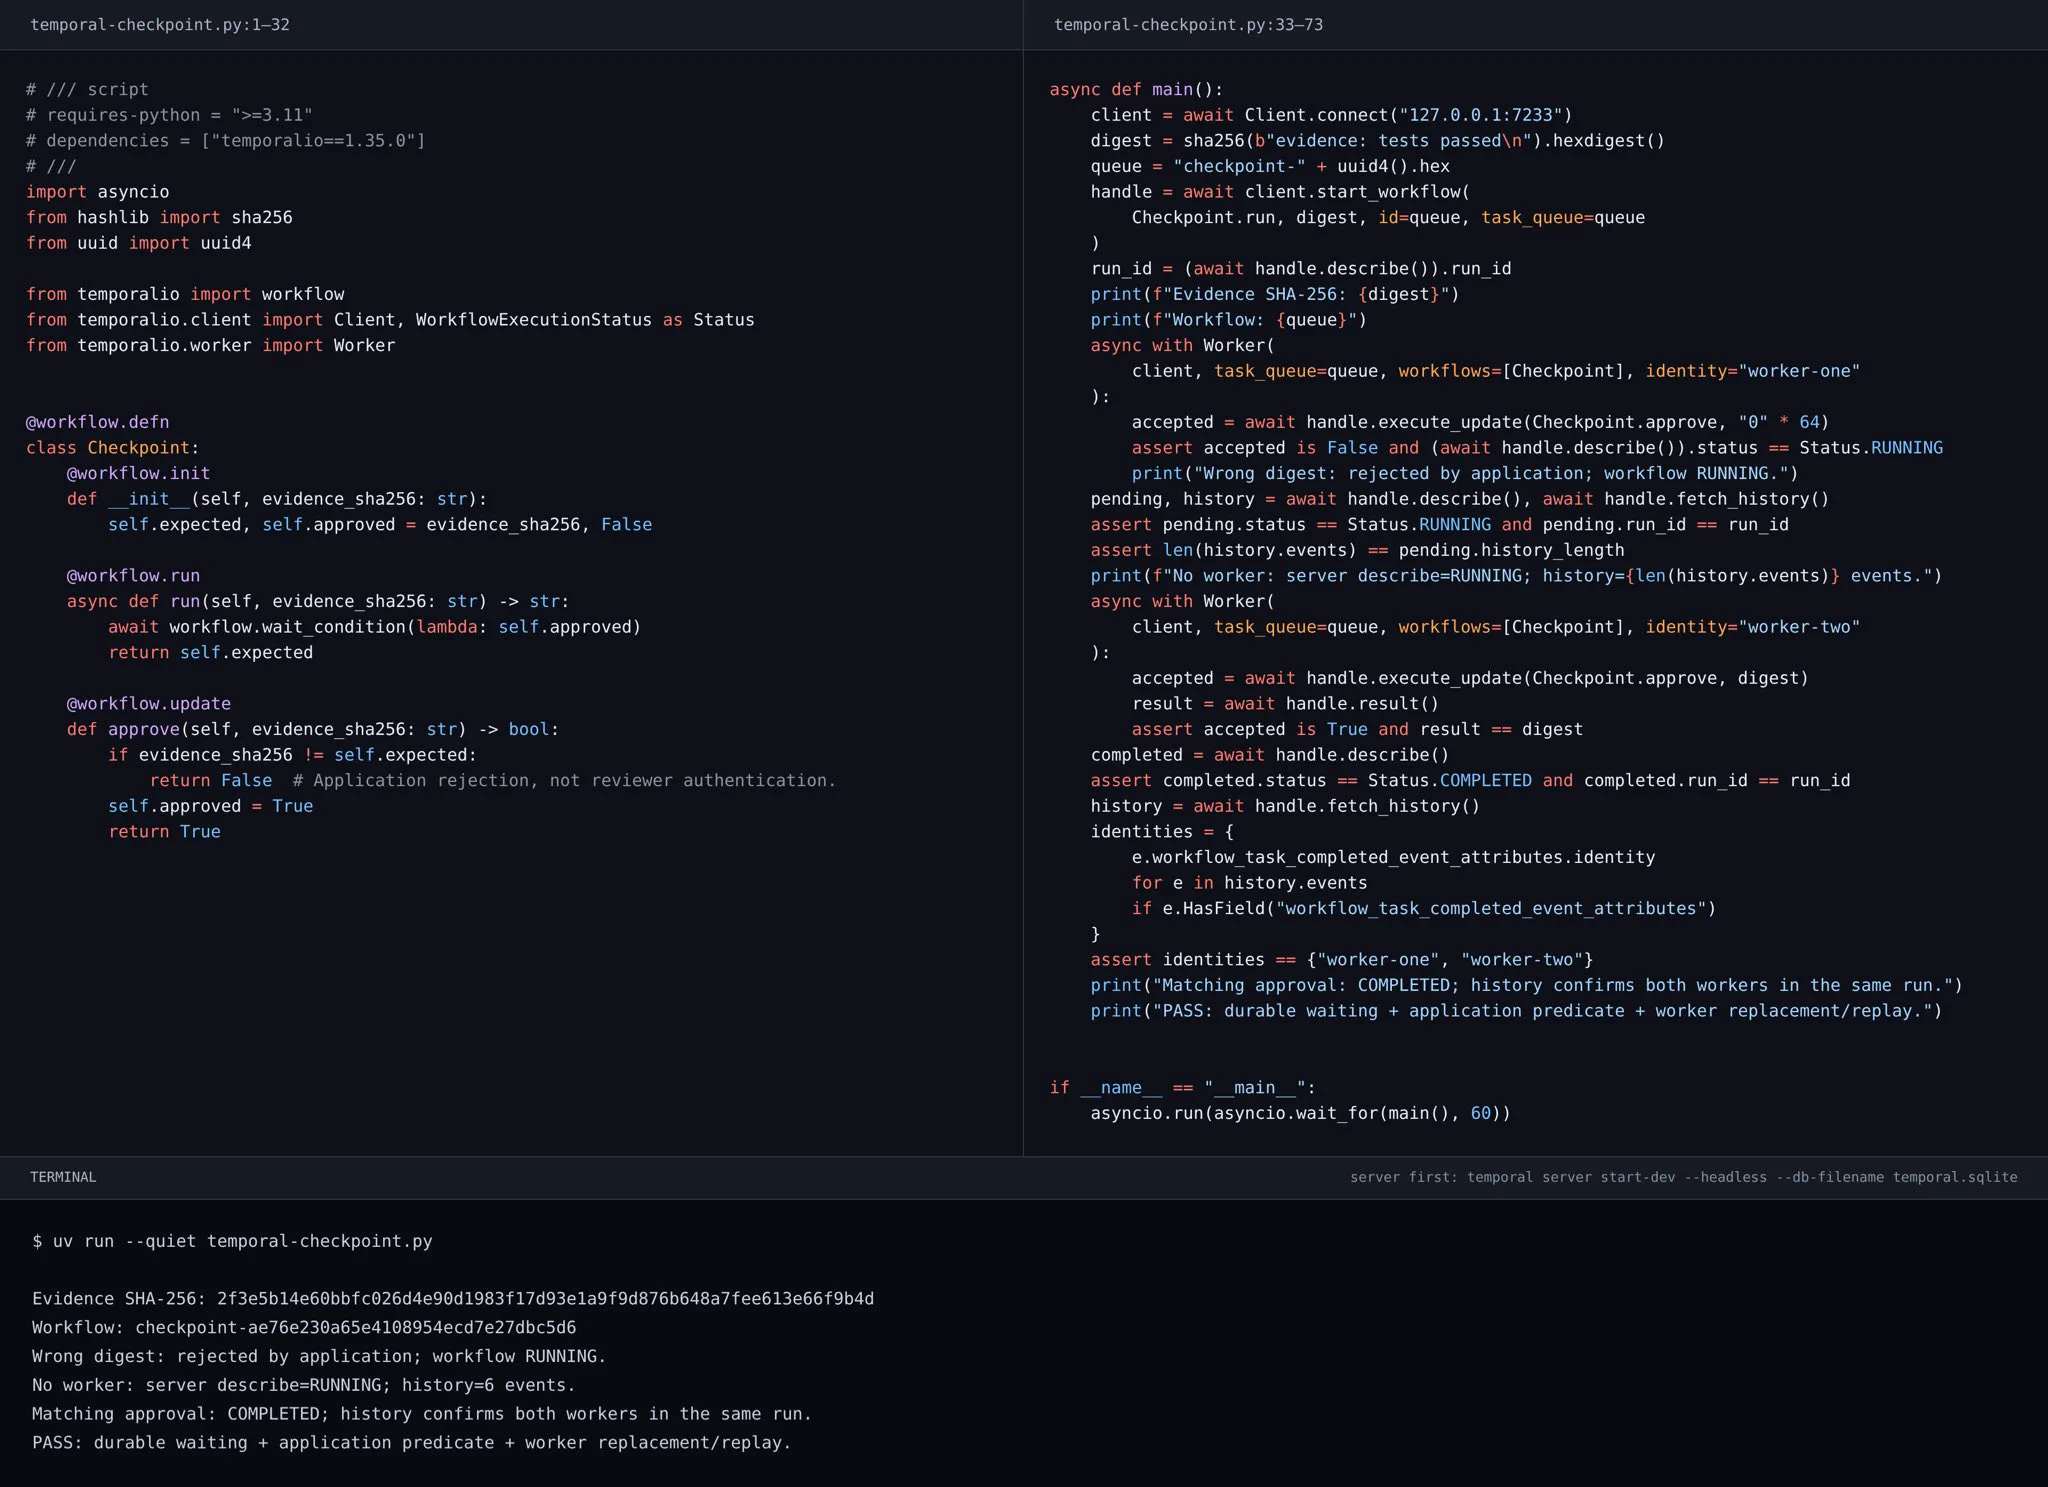
- Temporal can wait for an external decision without repeatedly invoking a model, and accept it only when the evidence matches.
Inference-time refinement and learning
Tests, executable checks, model judges. There are many ways to refer to these, but they’re almost all different names for something every AI engineer already knows about: evaluations.
For example, Prime Intellect’s verifiers can define tasks, run agents and harnesses, and score them, for evaluations or for training.
In their Kuhn poker example, the environment:
- Asks the agent for a move.
- Checks whether it is legal.
- Accepts a valid move (or explains the failure and asks again).
- Stops after a configured retry allowance, and the agent forfeits the hand.
That is already a small “act, verify, revise” loop. Replacing move validation with a test suite or an evidence check is a reasonable extension.
This is called inference-time refinement: the agent can revise its answer without any model weights changing.
RL turns the verifier’s assessment into a learning signal. A retry loop helps an agent improve its current attempt. Reinforcement learning changes the model so that future attempts are more likely to succeed.
For example, suppose the task is to produce code that passes trusted tests:
- The model generates several attempts, potentially using tools and revising its work.
- The verifier scores the outcomes.
- Prime Intellect’s prime-rl then computes group-relative training credit from those rewards.
- Then the prime-rl trainer updates the model’s weights, making the higher-reward behavior more probable.
So, we have gone from externally correcting an agent to teaching it better execution habits.
Interrupting the loop from inside the model
But why stop here?
Could we interrupt the loop from inside the model?
What if we give Qwen3.5-4B, running in OpenCode, this instruction:
Read /app/approval.json until it exists. Keep retrying, not replying.
Then we’d try to get it to ask whether to wait instead.
We don’t need to begin with an expensive reinforcement-learning run to test this idea. I connected OpenCode 2.2.5 to a 4-bit quantized Qwen3.5-4B, served locally with llama.cpp, running on four vCPUs, 8 GiB of RAM, and no GPU.
With Prime Intellect’s verifiers, I recorded the actual model calls, tool results, file state, and termination behavior. Then I added instrumentation to llama.cpp to record and modify intermediate activations without updating the model’s weights.
The unpatched agent reached 100 failed reads before the test stopped it. This, of course, is what I was looking for at this stage.
My next step was to find a reference for something other than retrying. So, I reconstructed the model request immediately after the first failed read of /app/approval.json. It still contained the read attempt and its “File not found” result, so I recorded the original retrying continuation as the retry reference. Then, for a separate question reference, I replaced only the user instruction:
Read /app/approval.json. When the file is absent and no retry budget was specified, ask me with the question tool how many attempts or how long to wait. Pause for my answer instead of polling.
Qwen generated a question tool call containing:
How many attempts or how long to wait for approval?
While it generated that response, the llama.cpp hook recorded 9,216 feed-forward activation values in each of 32 layers. The snapshot I used came from output step 14, where the continuation generated the token ask .
That gave me a concrete reference from a question-producing continuation.
I could then test whether transferring some of those activations into the original retrying run changed its behavior.
Not every patch worked. Some smaller patches looked promising in isolated, empty-cache replays, but failed in native OpenCode.
The patch that worked was broad: 184,320 activation values across layers 12–31. Not exactly one neuron. During inference, the hook compared the running model’s layer-12 activations with that reference. When they matched closely enough, it replaced the activations in layers 12–31 with the question-producing values.
With the patch enabled, native OpenCode made one unsuccessful read and asked:
Should I wait for /app/approval.json to be created before proceeding?
Finally, the model had stopped the loop.
Controls, limits, and reproduction
But this was just one run. So I repeated it.
The zeroed and shuffled patches still reached their 12-read screening limits. Turning the patch off restored the exact 100-read baseline. Normal cache reuse remained enabled between model calls. The successful result was not confined to an empty-cache replay.
No reinforcement learning was involved, no classical fine-tuning was necessary either, and, more importantly, this is cheap to reproduce.
There are, of course, limits to this result. This is a toy scenario. It does not give us a general loop detector, or a neuron that represents good judgment. But it shows a direction. We can make failures measurable. We can use a verifier to test interventions inside the model. We can start with a small CPU, even. The tools are already in our hands.
The code and reproduction steps are in this gist.